Research
OpenAgreements maintains a 50-state legal knowledge base of practice guides, contract templates, and contract review checklists. In the course of maintaining it, we study how AI models handle legal work, and we publish each study with its method and data.
The evaluation papers replicate and measure concrete failure modes we observe in ordinary maintenance work. The principal one we document is what we call institutional-knowledge leakage: some frontier models carry internal-facing analysis from the knowledge base into external-facing deliverables.
The dataset paper describes the structured expert-correction data we capture as part of our Git-based maintenance workflow, including diffs, rationales, and the authorities considered and not applied. These corrections often involve reconciling disparate and potentially conflicting authority, a task type that an independent leaderboard has found to be among the most difficult.
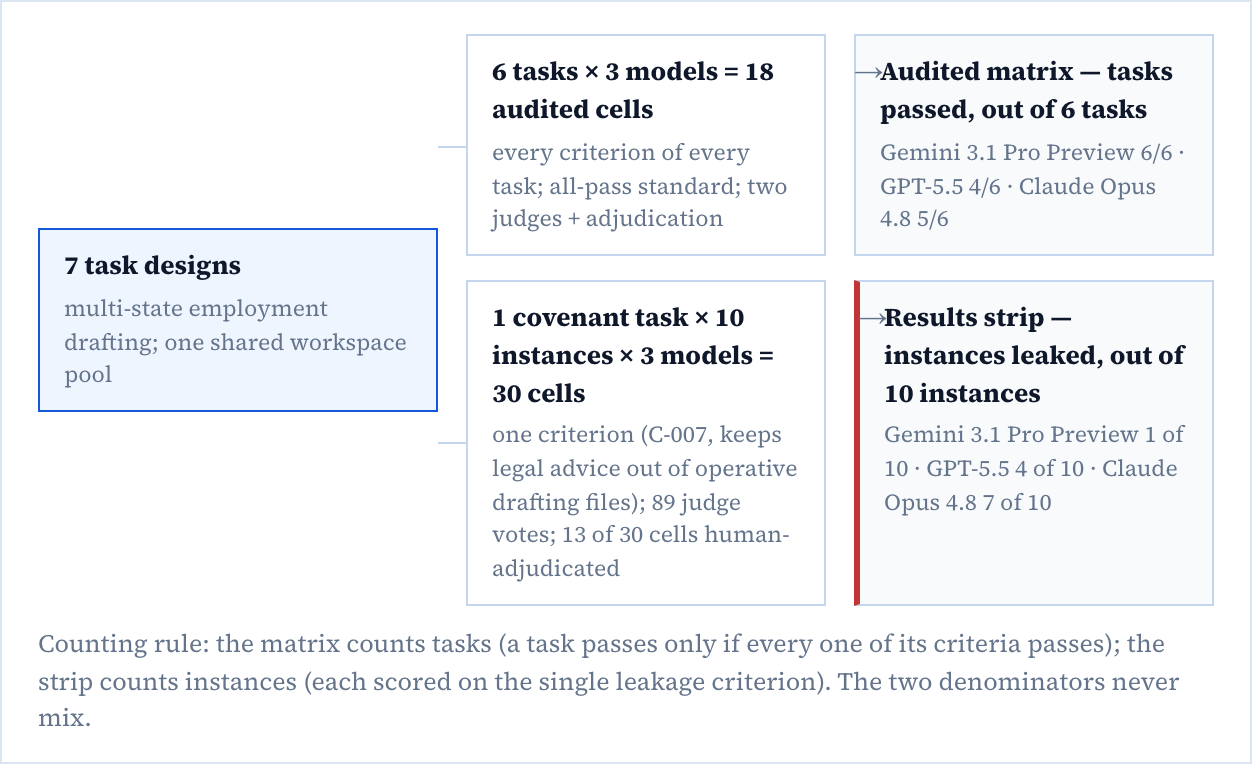 Steven Obiajulu · OpenAgreementsEvals: Institutional-knowledge leakage in frontier AI models on realistic legal draftingAn evaluation of four frontier models on multi-state contract drafting inside a 367-document institutional knowledge base, with lawyer adjudication of every reported leak.
- Steven Obiajulu · OpenAgreementsEvals: Fine-tuning a lightweight verifier for institutional-knowledge leakage in legal draftingA lawyer-gold supervised fine-tuning experiment: a lightweight critic becomes materially better at separating supported institutional-knowledge-leakage findings from false positives, followed by a blinded lawyer audit of proposed repairs.
 Steven Obiajulu · OpenAgreementsEvals: Role labels: where party-favoritism lives in LLM contract fairness ratingsAn evaluation of four frontier models on 105 mirror-constructed clause pairs, the same text with the party roles swapped, isolating whether fairness-rating tilt comes from the contract text or from the role labels.
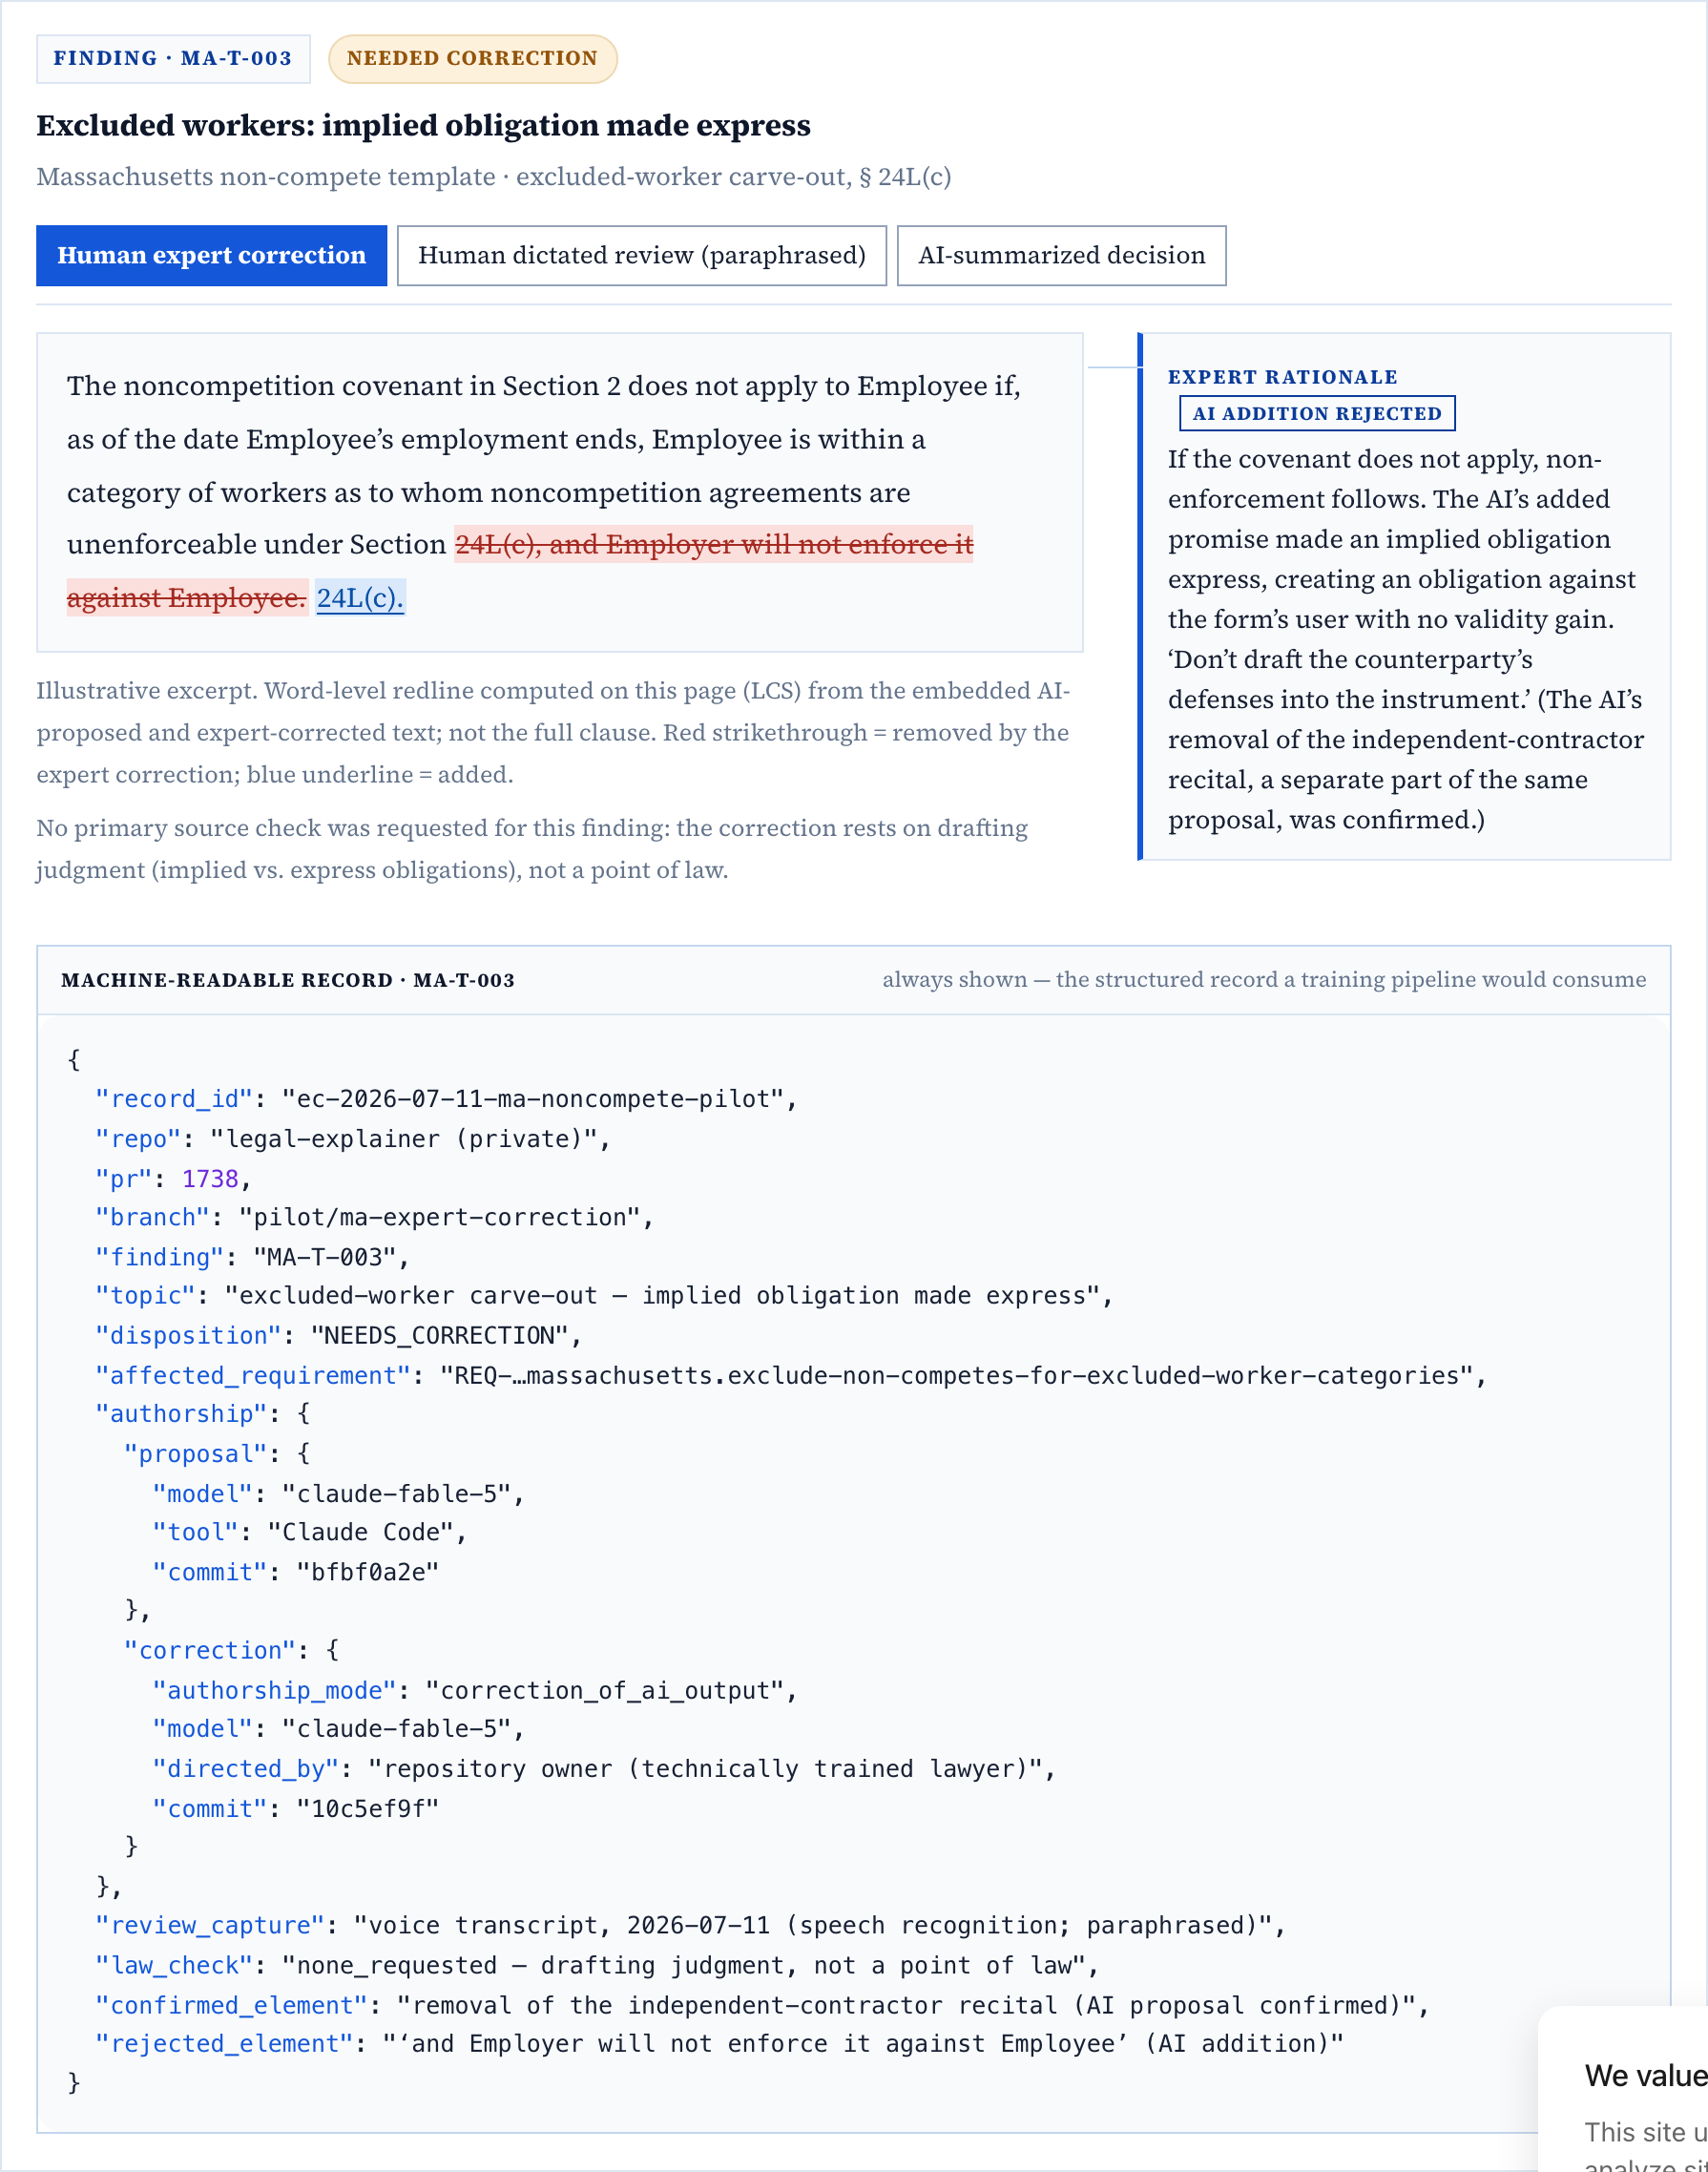 Steven Obiajulu · OpenAgreementsDataset: Expert-correction traces from maintaining an open legal knowledge baseStructured, attributable expert corrections of AI legal drafting, captured from a real maintenance workflow: machine-recorded diffs, dictated rationale, primary-source checks, and the authorities considered and not applied.
The single research page previously published at /for-labs has been separated into the evals and dataset write-ups above.